
EPISODE · Oct 1, 2026 · 24 MIN
Theoretical Limits of Language Model Alignment
from Best AI papers explained · host Enoch H. Kang
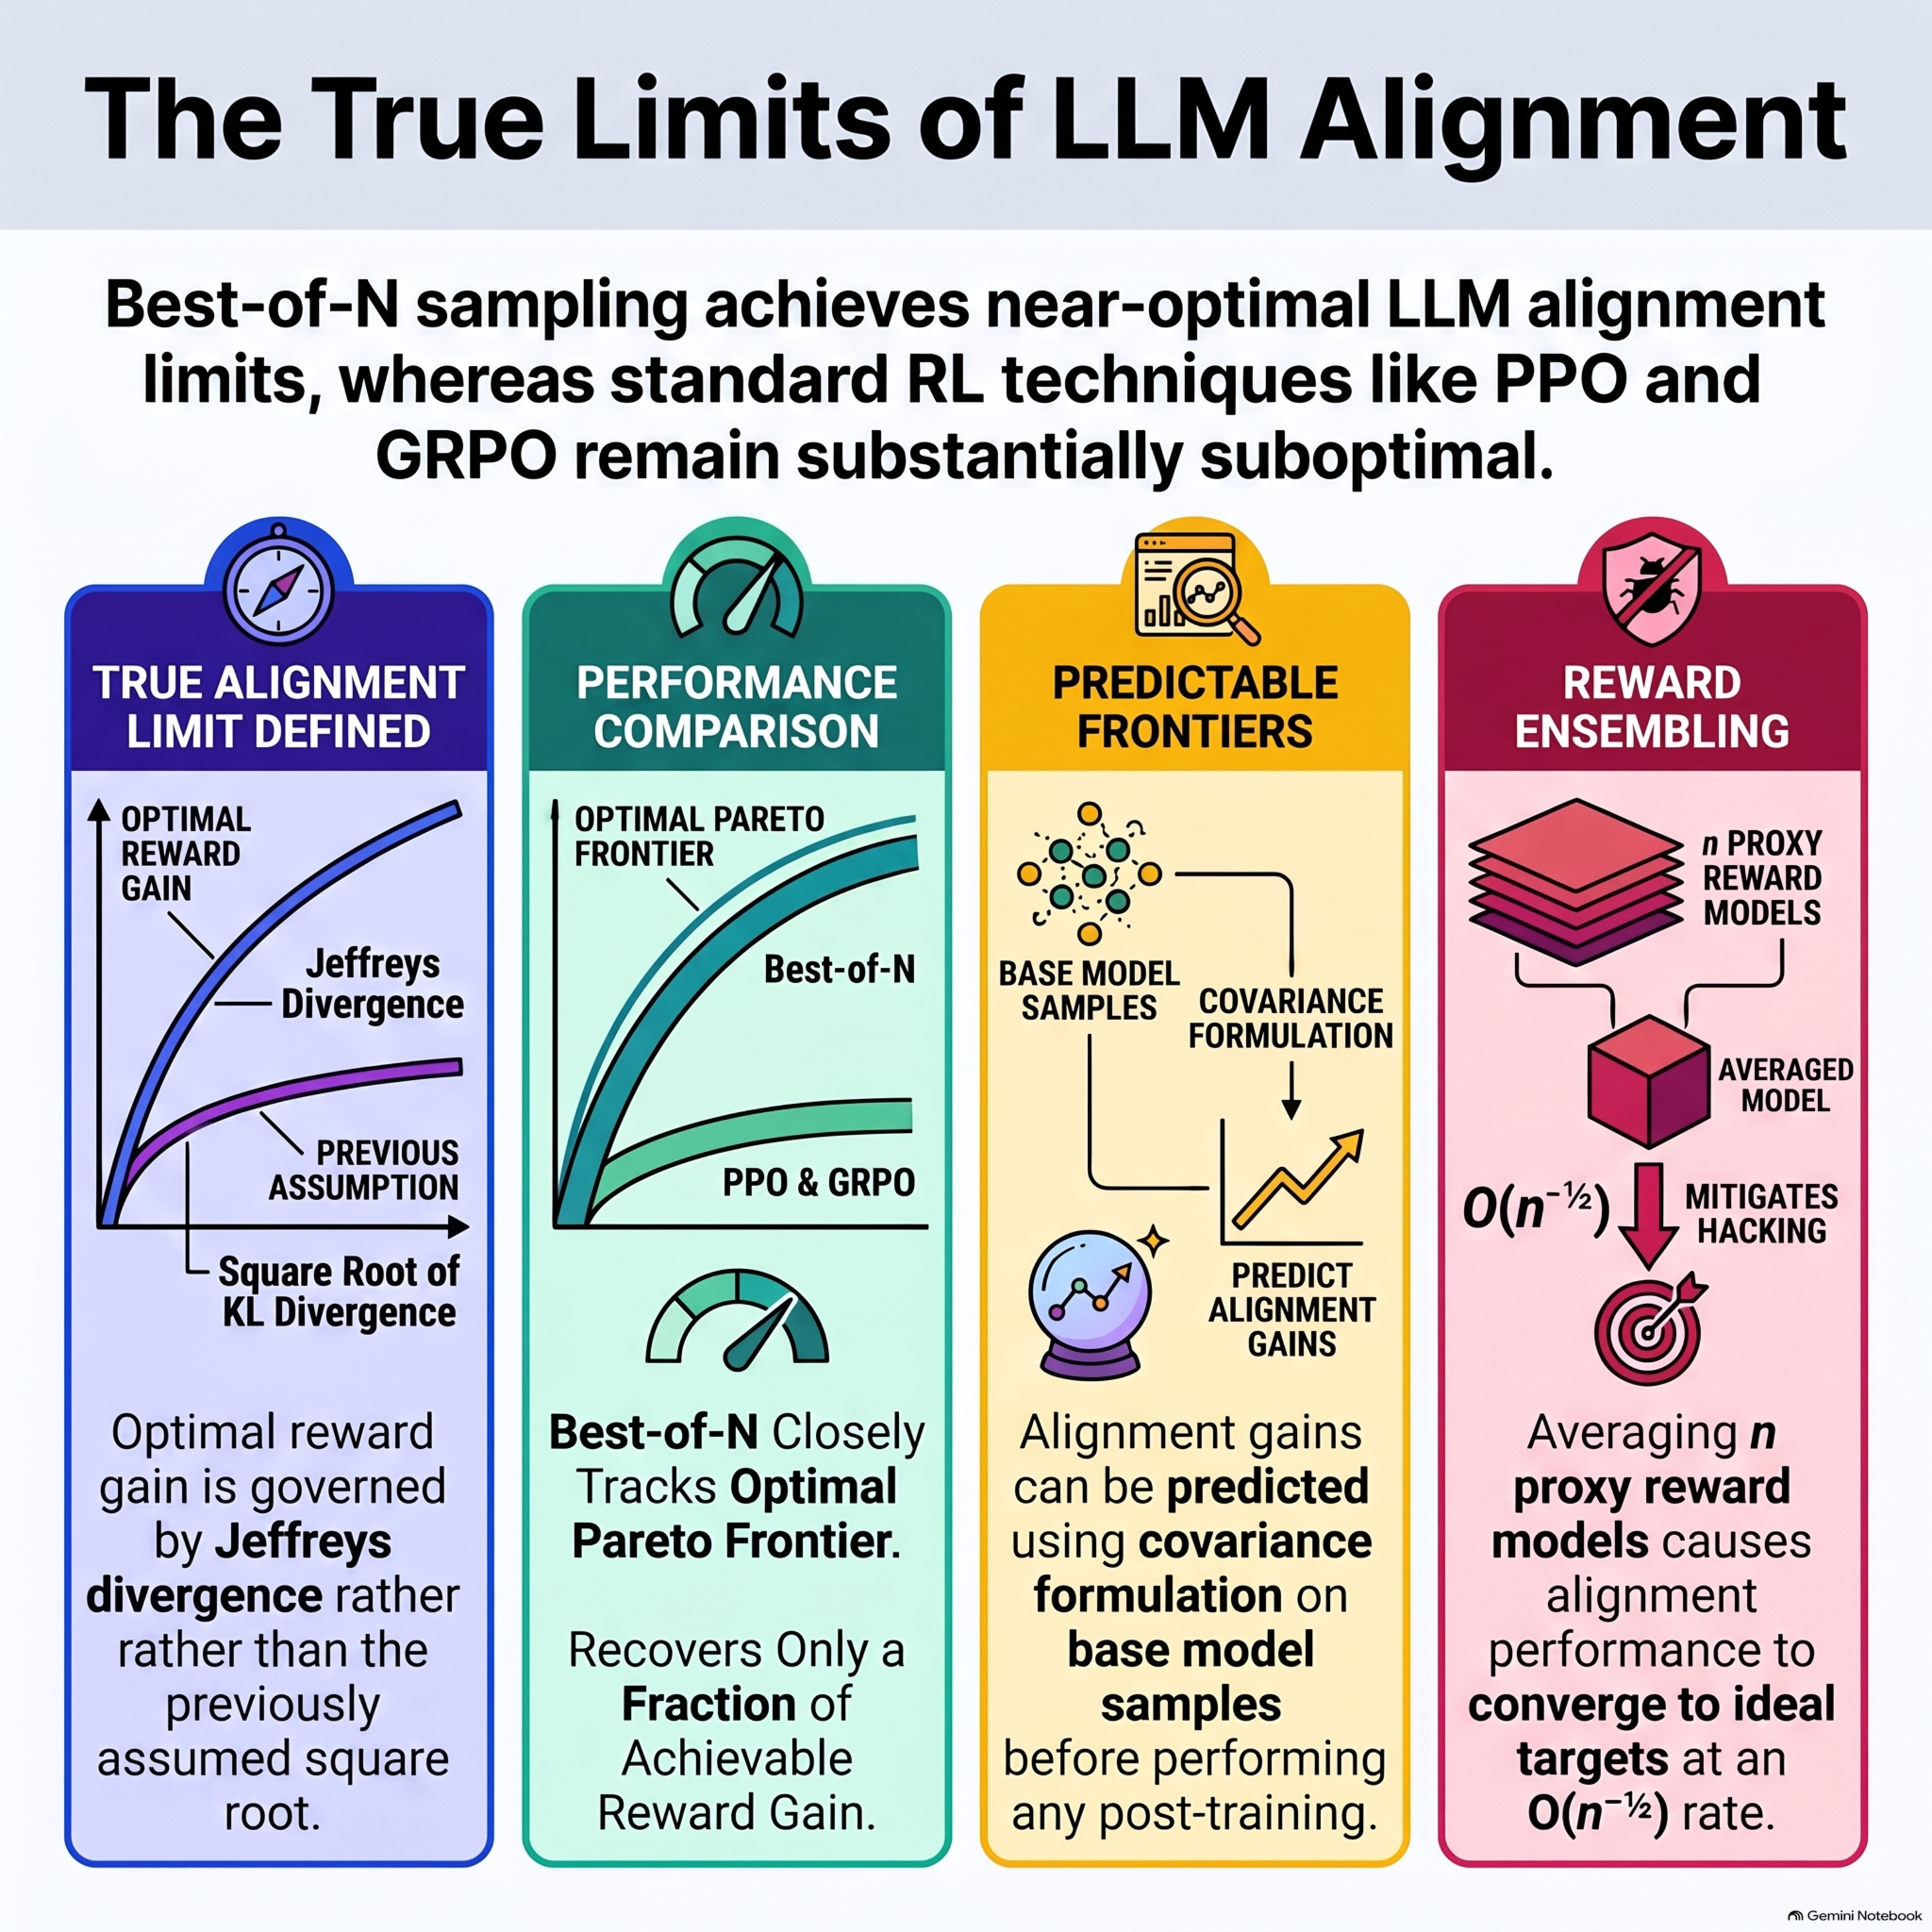
This paper investigate the fundamental limits of language model alignment by establishing exact theoretical boundaries for reward improvement under a KL-divergence constraint using Jeffreys divergence and a computable covariance estimator. They demonstrate that best-of-N sampling closely approaches this theoretical Pareto frontier, whereas gradient-based methods like PPO and GRPO remain suboptimal. Additionally, the literature analyzes how proxy reward errors drive performance degradation and reward hacking, while proving that reward ensemblingsuccessfully mitigates these issues at a convergence rate of O(n⁻¹ᐟ²).
Embed this episode
Ready to play
Theoretical Limits of Language Model Alignment
No transcript for this episode yet
Similar Episodes
No similar episodes found.