Trajectory Bellman Residual Minimization: A Simple Value-Based Method for LLM Reasoning
from Best AI papers explained Hosted by Enoch H. Kang
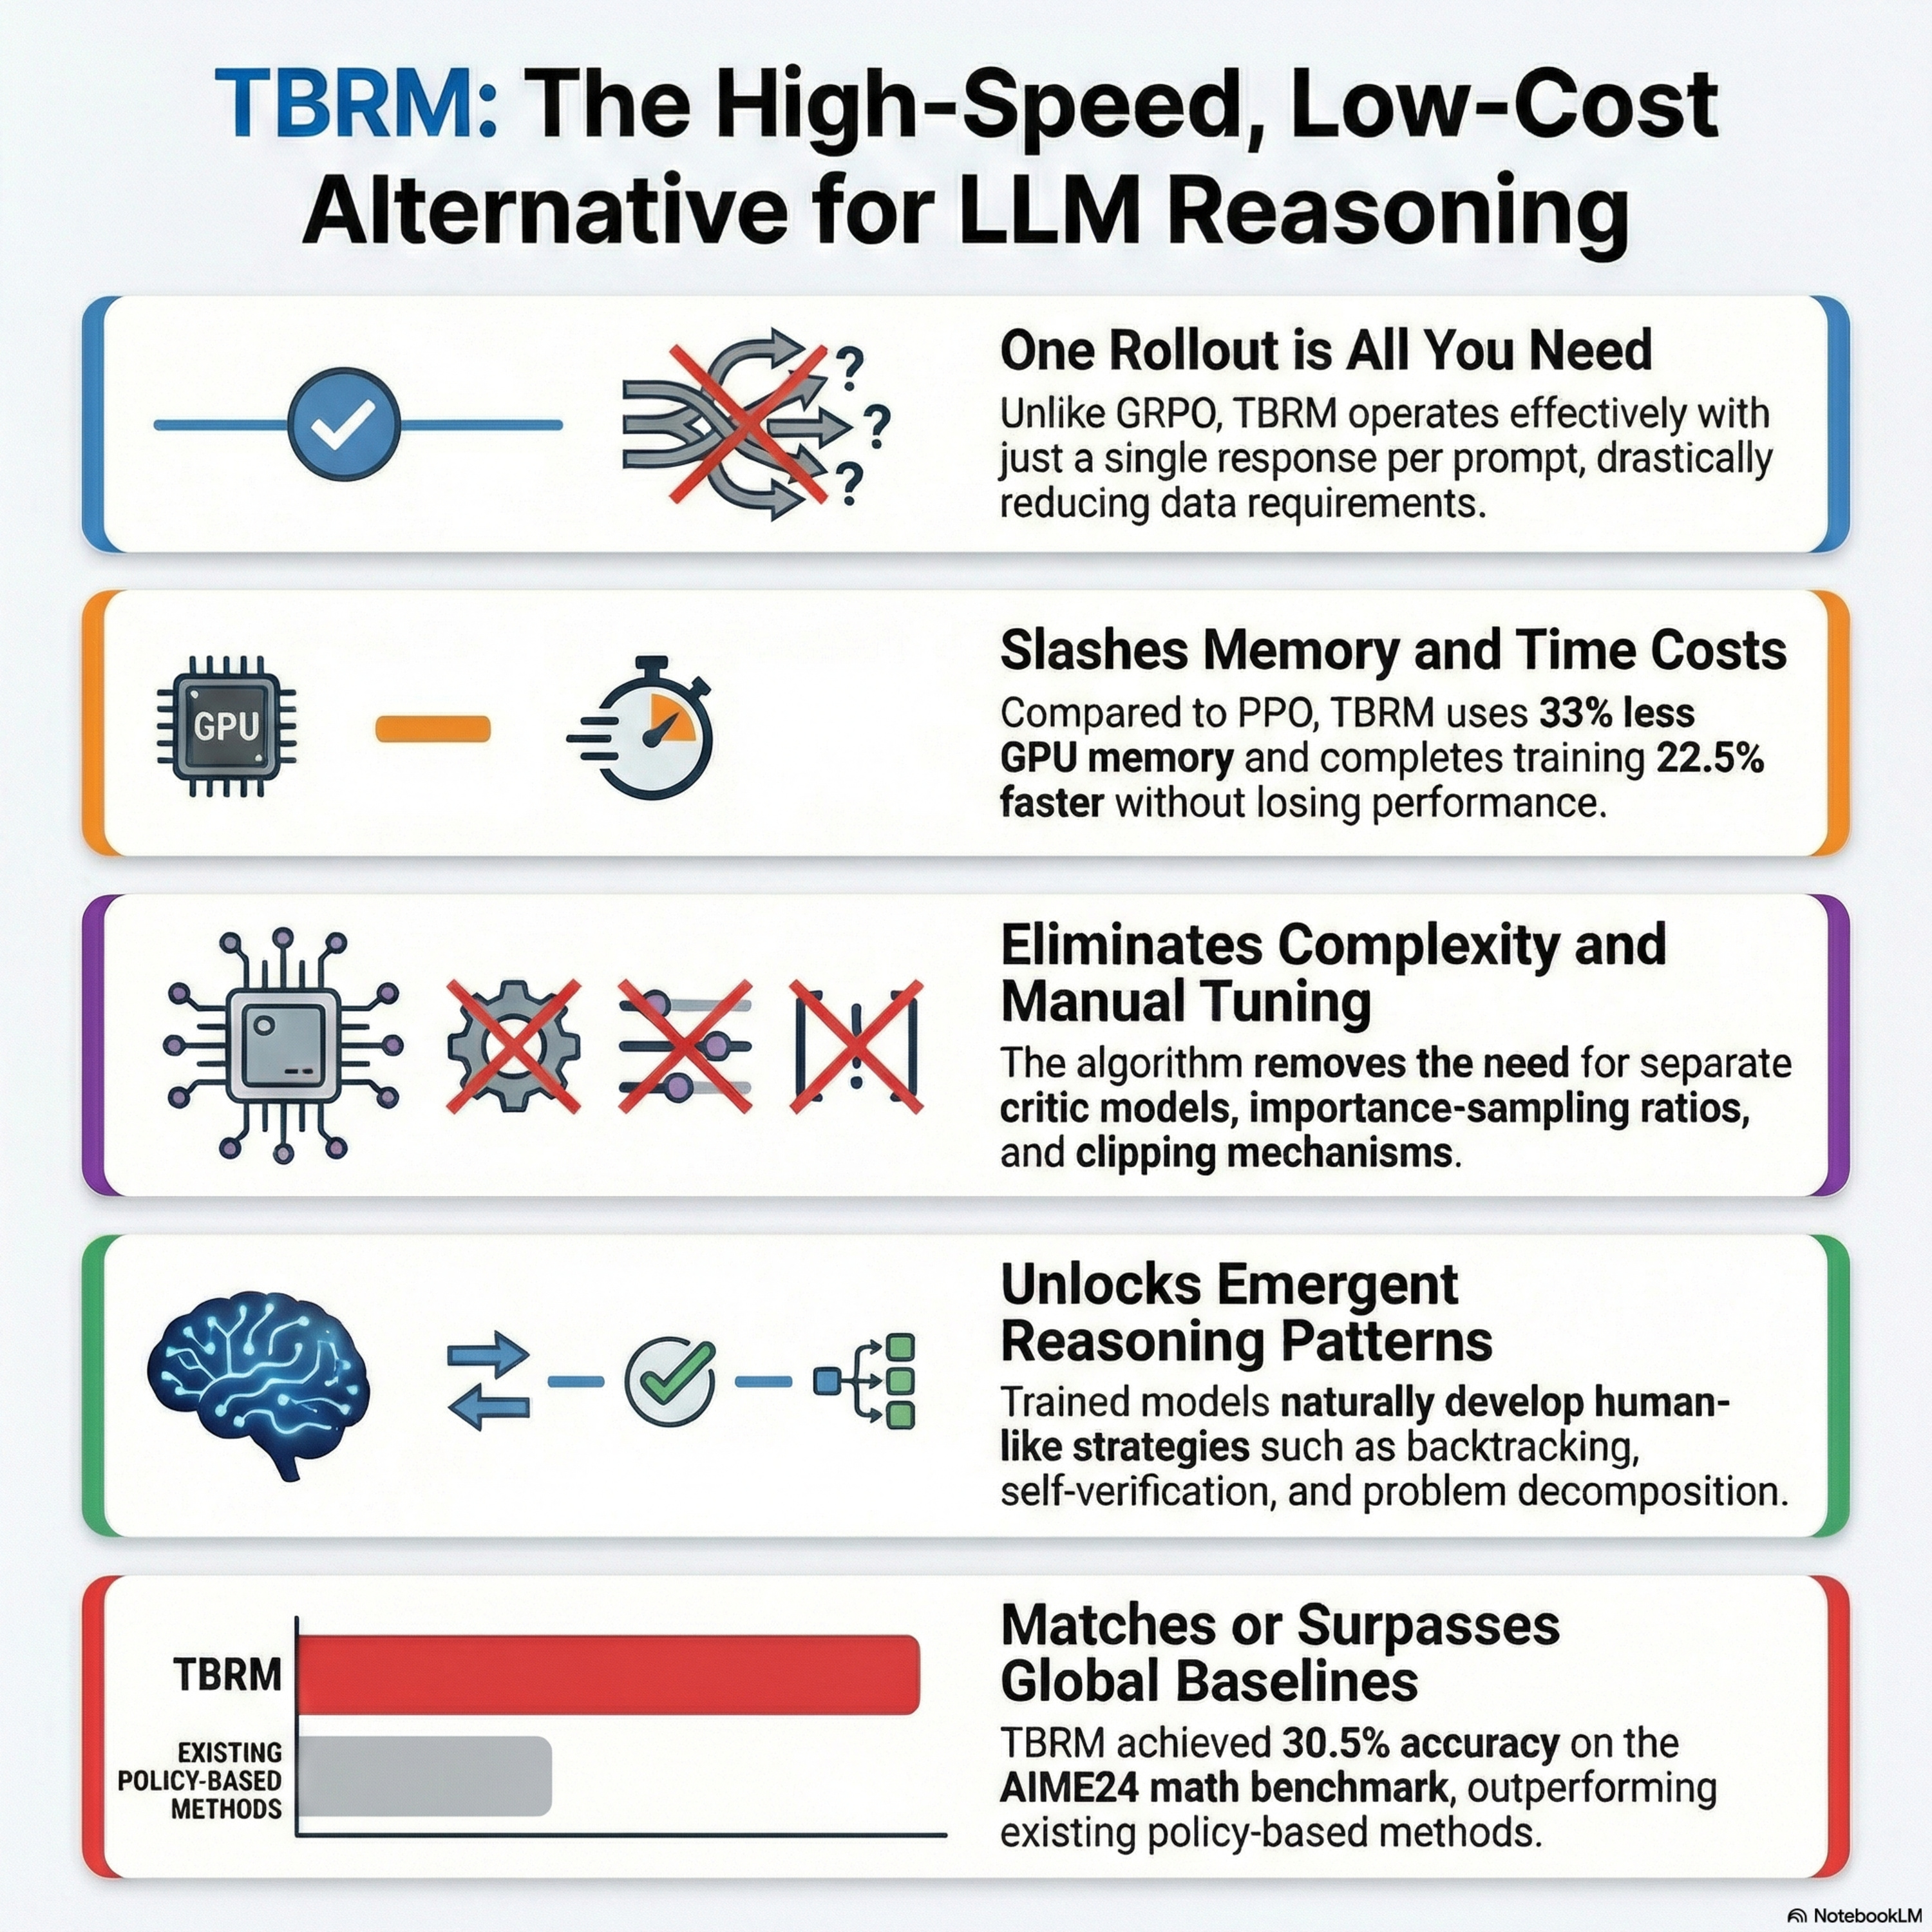
This paper introduces Trajectory Bellman Residual Minimization (TBRM), a new value-based reinforcement learning algorithm designed to improve the reasoning capabilities of large language models. Unlike traditional policy-based methods like PPO or GRPO, TBRM optimizes a single trajectory-level objective using the model's own raw outputs as Q-values. This streamlined approach removes the need for complex components like critic models, importance sampling, or clipping, significantly reducing computational and memory overhead. The authors provide a theoretical proof of convergence to an optimal policy even when using arbitrary off-policy data in deterministic environments. Empirical tests on mathematical reasoning benchmarks show that TBRM matches or exceeds the performance of established baselines while being faster and more resource-efficient. Ultimately, the research suggests that value-based RL is a principled and powerful alternative for training models to handle complex, multi-step thinking tasks.
Embed this episode
No transcript yet.