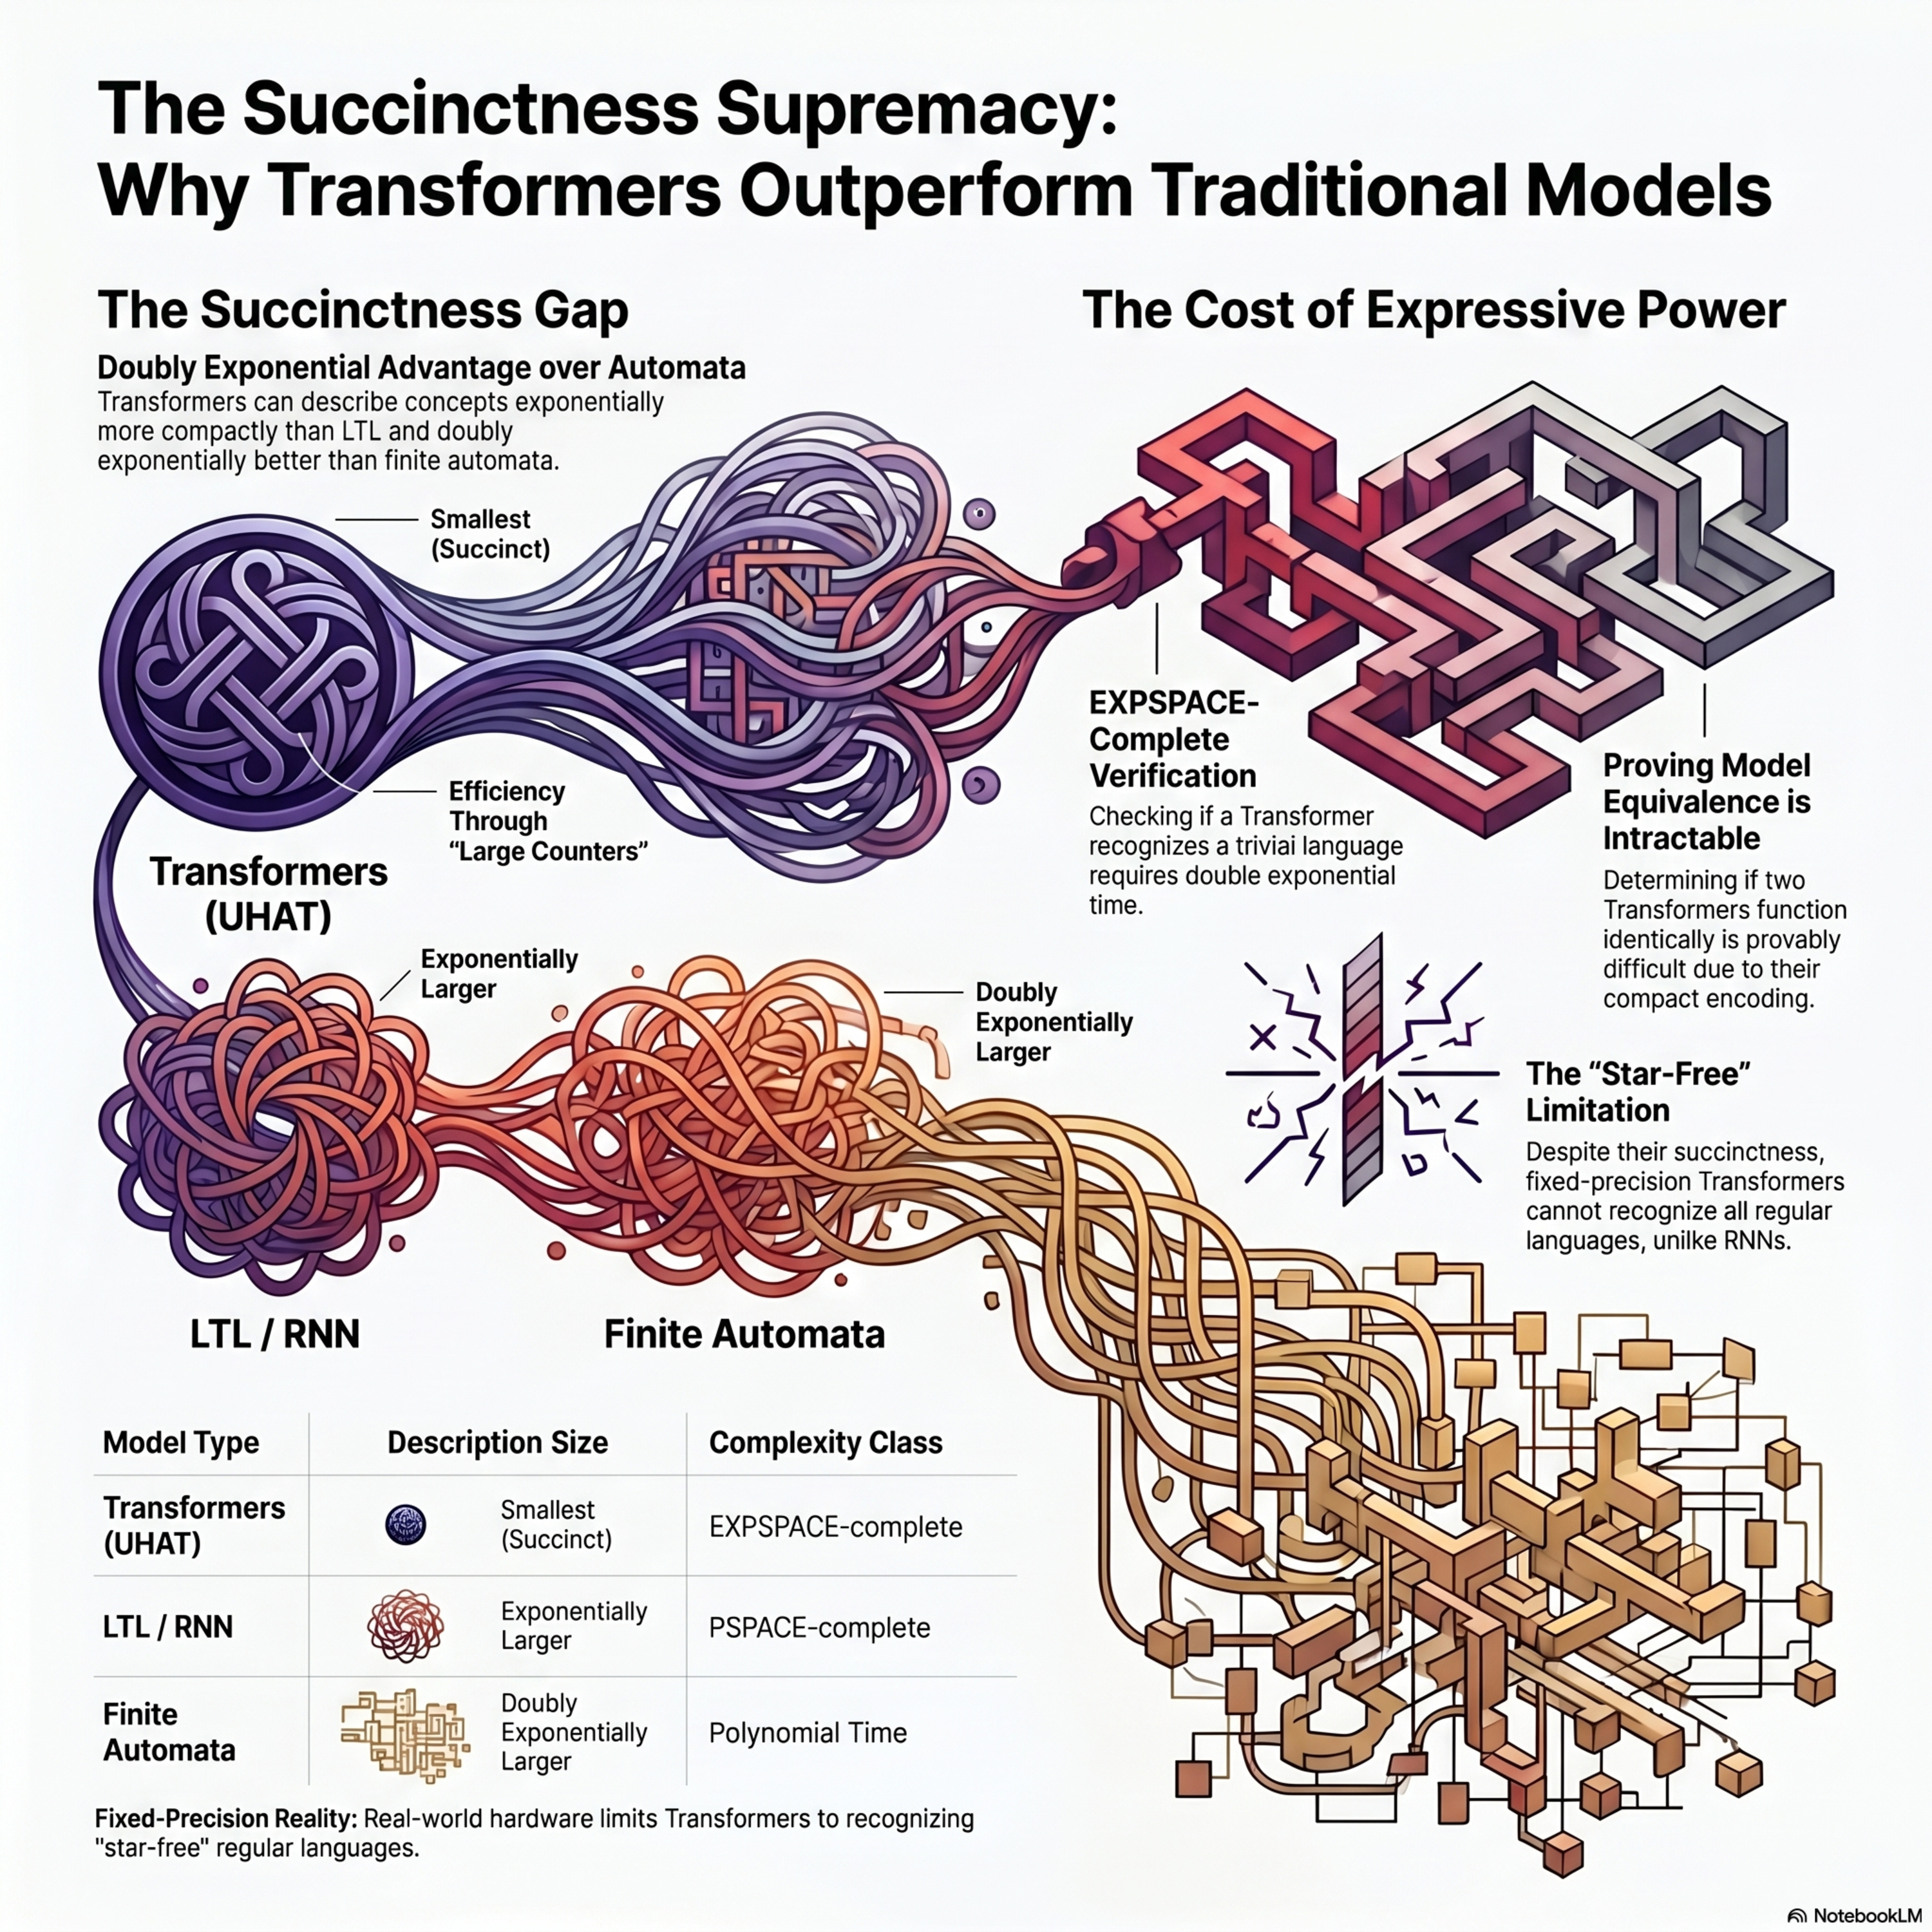
Transformers are inherently succint
from Best AI papers explained Hosted by Enoch H. Kang
This paper details research proving that **fixed-precision transformers** possess immense **succinctness**, allowing them to represent complex concepts with far fewer parameters than traditional models. By simulating large binary counters through **unique hard-attention mechanisms**, transformers can describe languages **exponentially more efficiently** than **Linear Temporal Logic (LTL)** or **Recurrent Neural Networks (RNNs)**. Furthermore, they achieve a **doubly exponential** size advantage over **finite automata** when encoding the same patterns. This extreme descriptional efficiency carries a computational cost, as **verifying basic properties** of these transformers, such as non-emptiness or equivalence, is proven to be **EXPSPACE-complete**. The authors also contribute a new **singly exponential translation** from transformers to LTL, refining previous theoretical bounds. Ultimately, the paper establishes that the power of transformers stems not just from what they can recognize, but from how **compactly** they can encode sophisticated logical structures.
Embed this episode
No transcript yet.