
EPISODE · Mar 22, 2026 · 11 MIN
TURNWISE: The Gap between Single- and Multi-turn Language Model Capabilities
from Best AI papers explained · host Enoch H. Kang
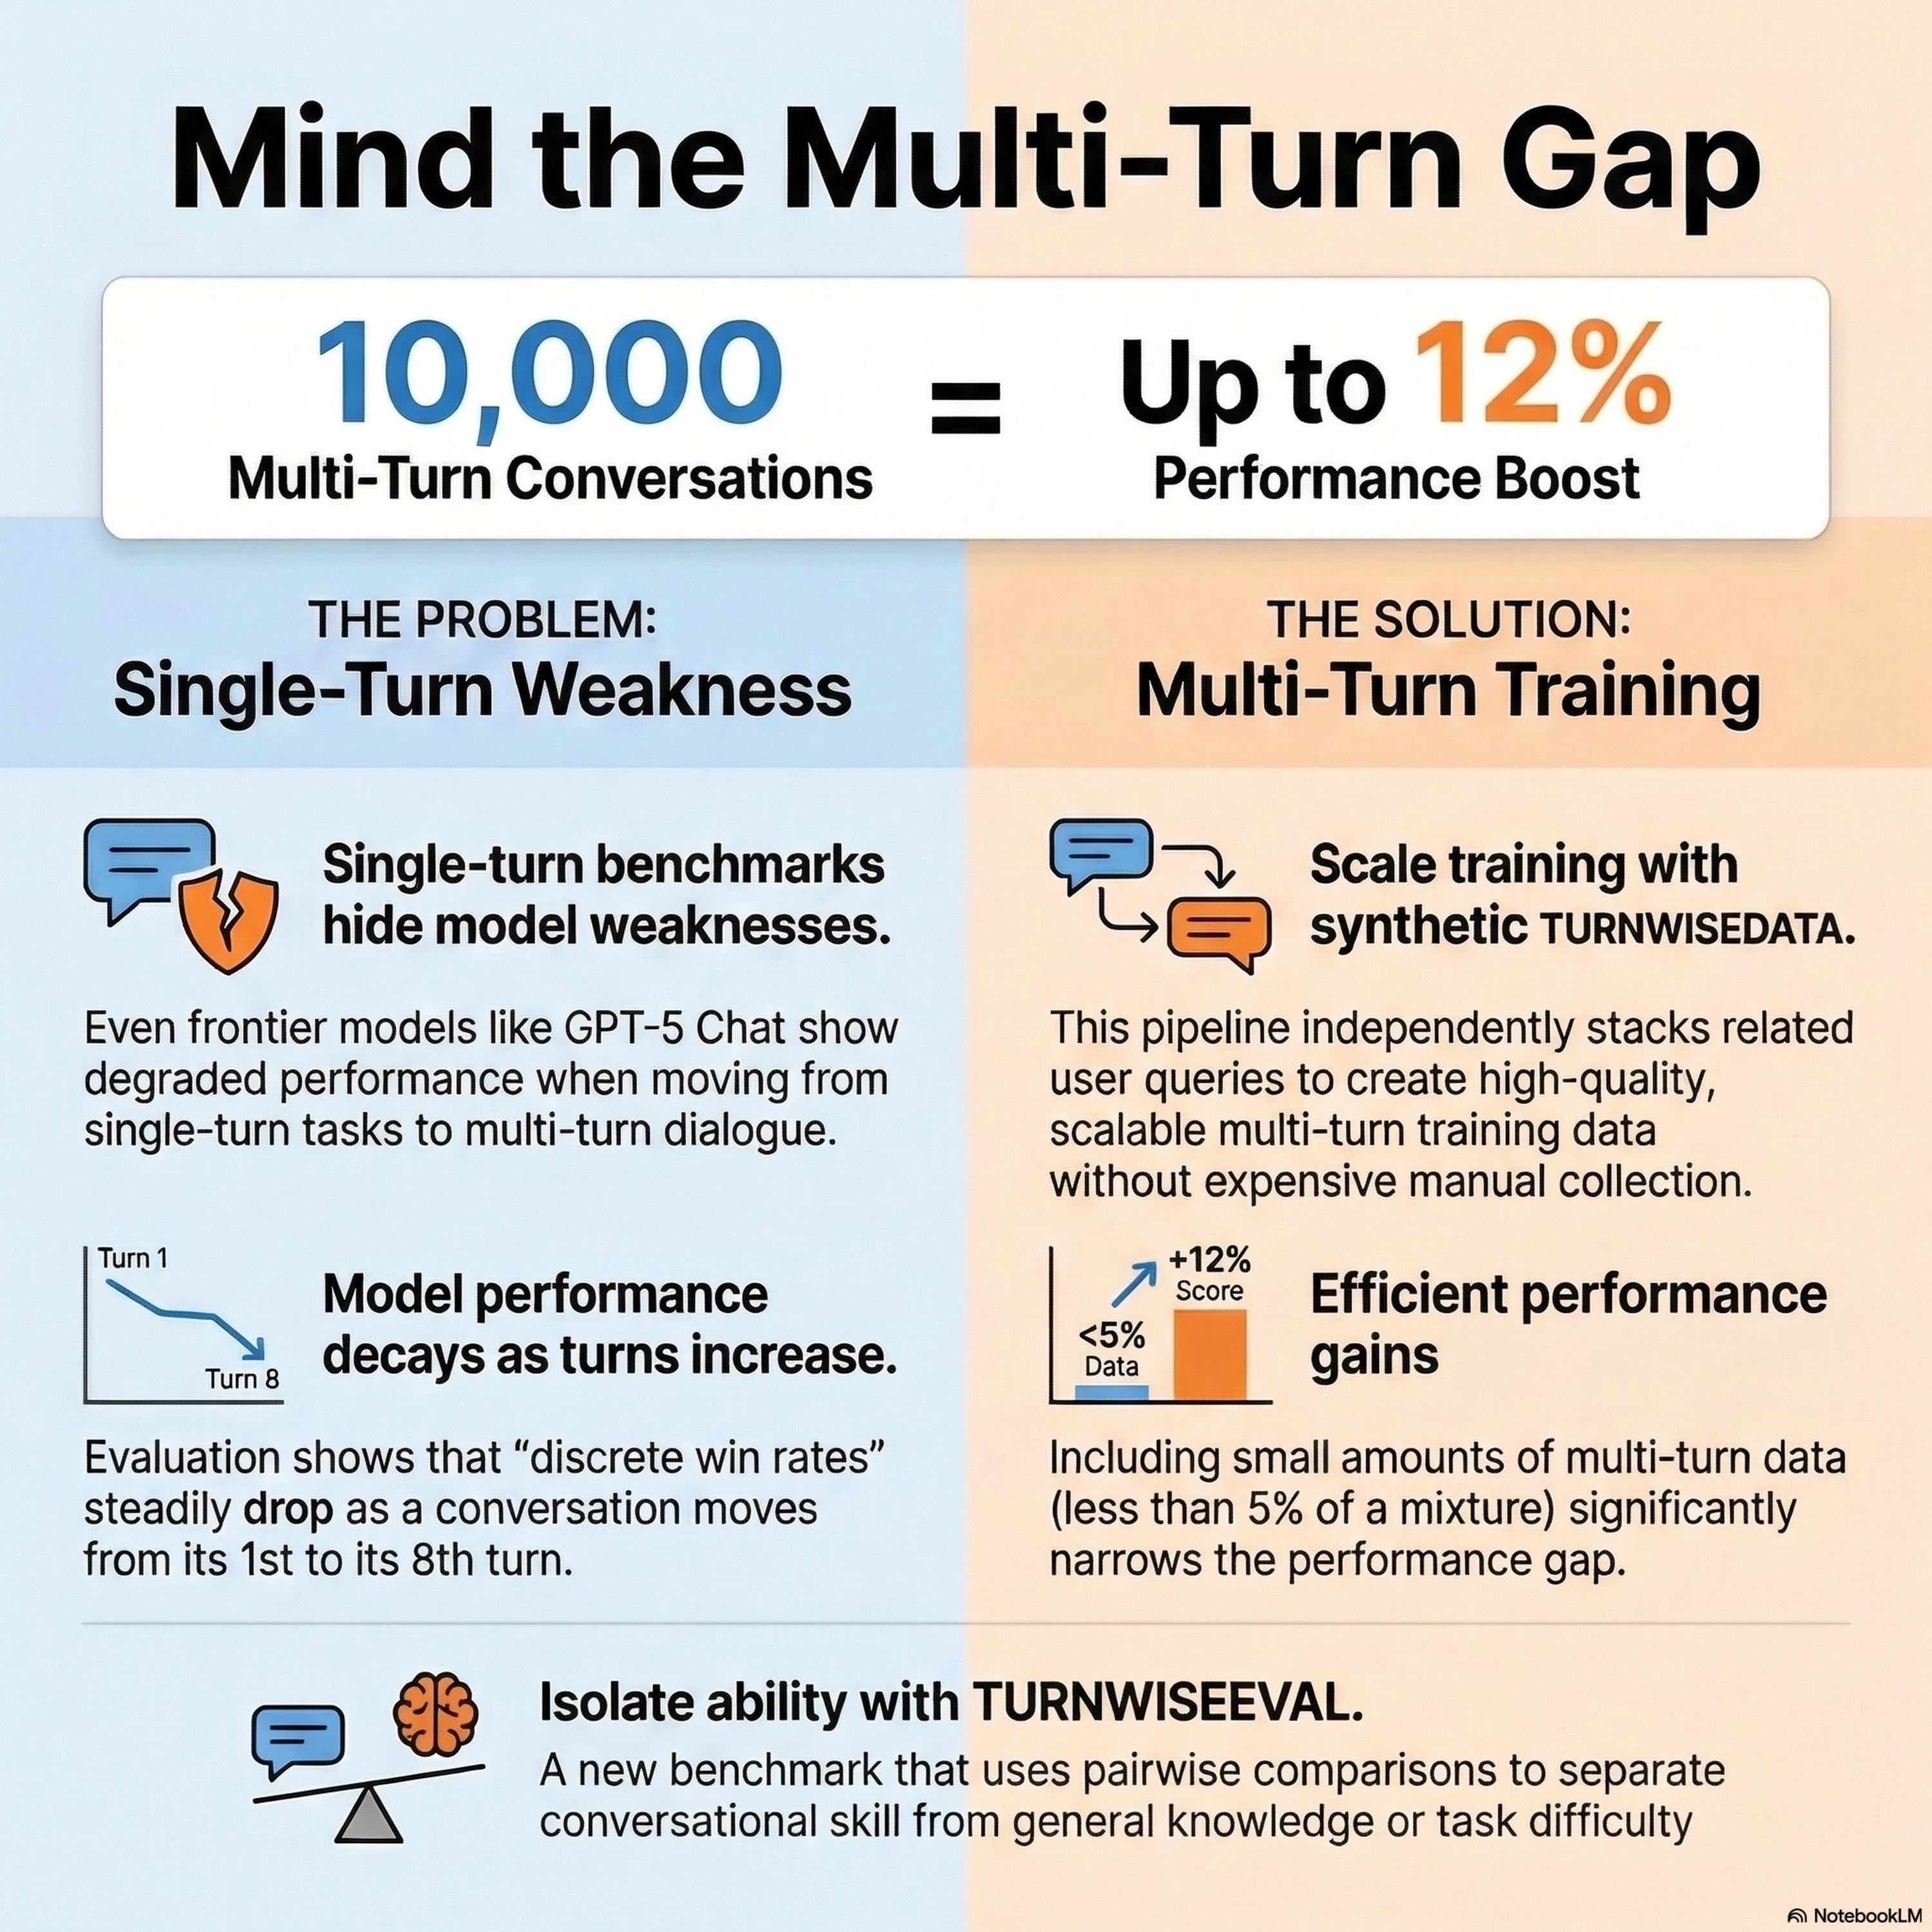
This research addresses the performance gap in large language models between single-turn and multi-turn interactions. The authors introduce TURNWISEEVAL, a new benchmark that isolates conversational ability by comparing model responses in long dialogues against equivalent single-turn prompts. To improve model performance, they also developed TURNWISEDATA, a scalable pipeline that generates synthetic multi-turn training data from existing single-turn instructions. Their experiments demonstrate that even advanced models often struggle with extended context, but incorporating a small amount of this synthetic data during training significantly boosts chat capabilities. Ultimately, the study highlights that multi-turn proficiency is a distinct skill set that requires dedicated evaluation and specialized training data.
Embed this episode
Ready to play
TURNWISE: The Gap between Single- and Multi-turn Language Model Capabilities
No transcript for this episode yet
Similar Episodes
No similar episodes found.