Understanding Reasoning from Pretraining to Post-Training
from Best AI papers explained Hosted by Enoch H. Kang
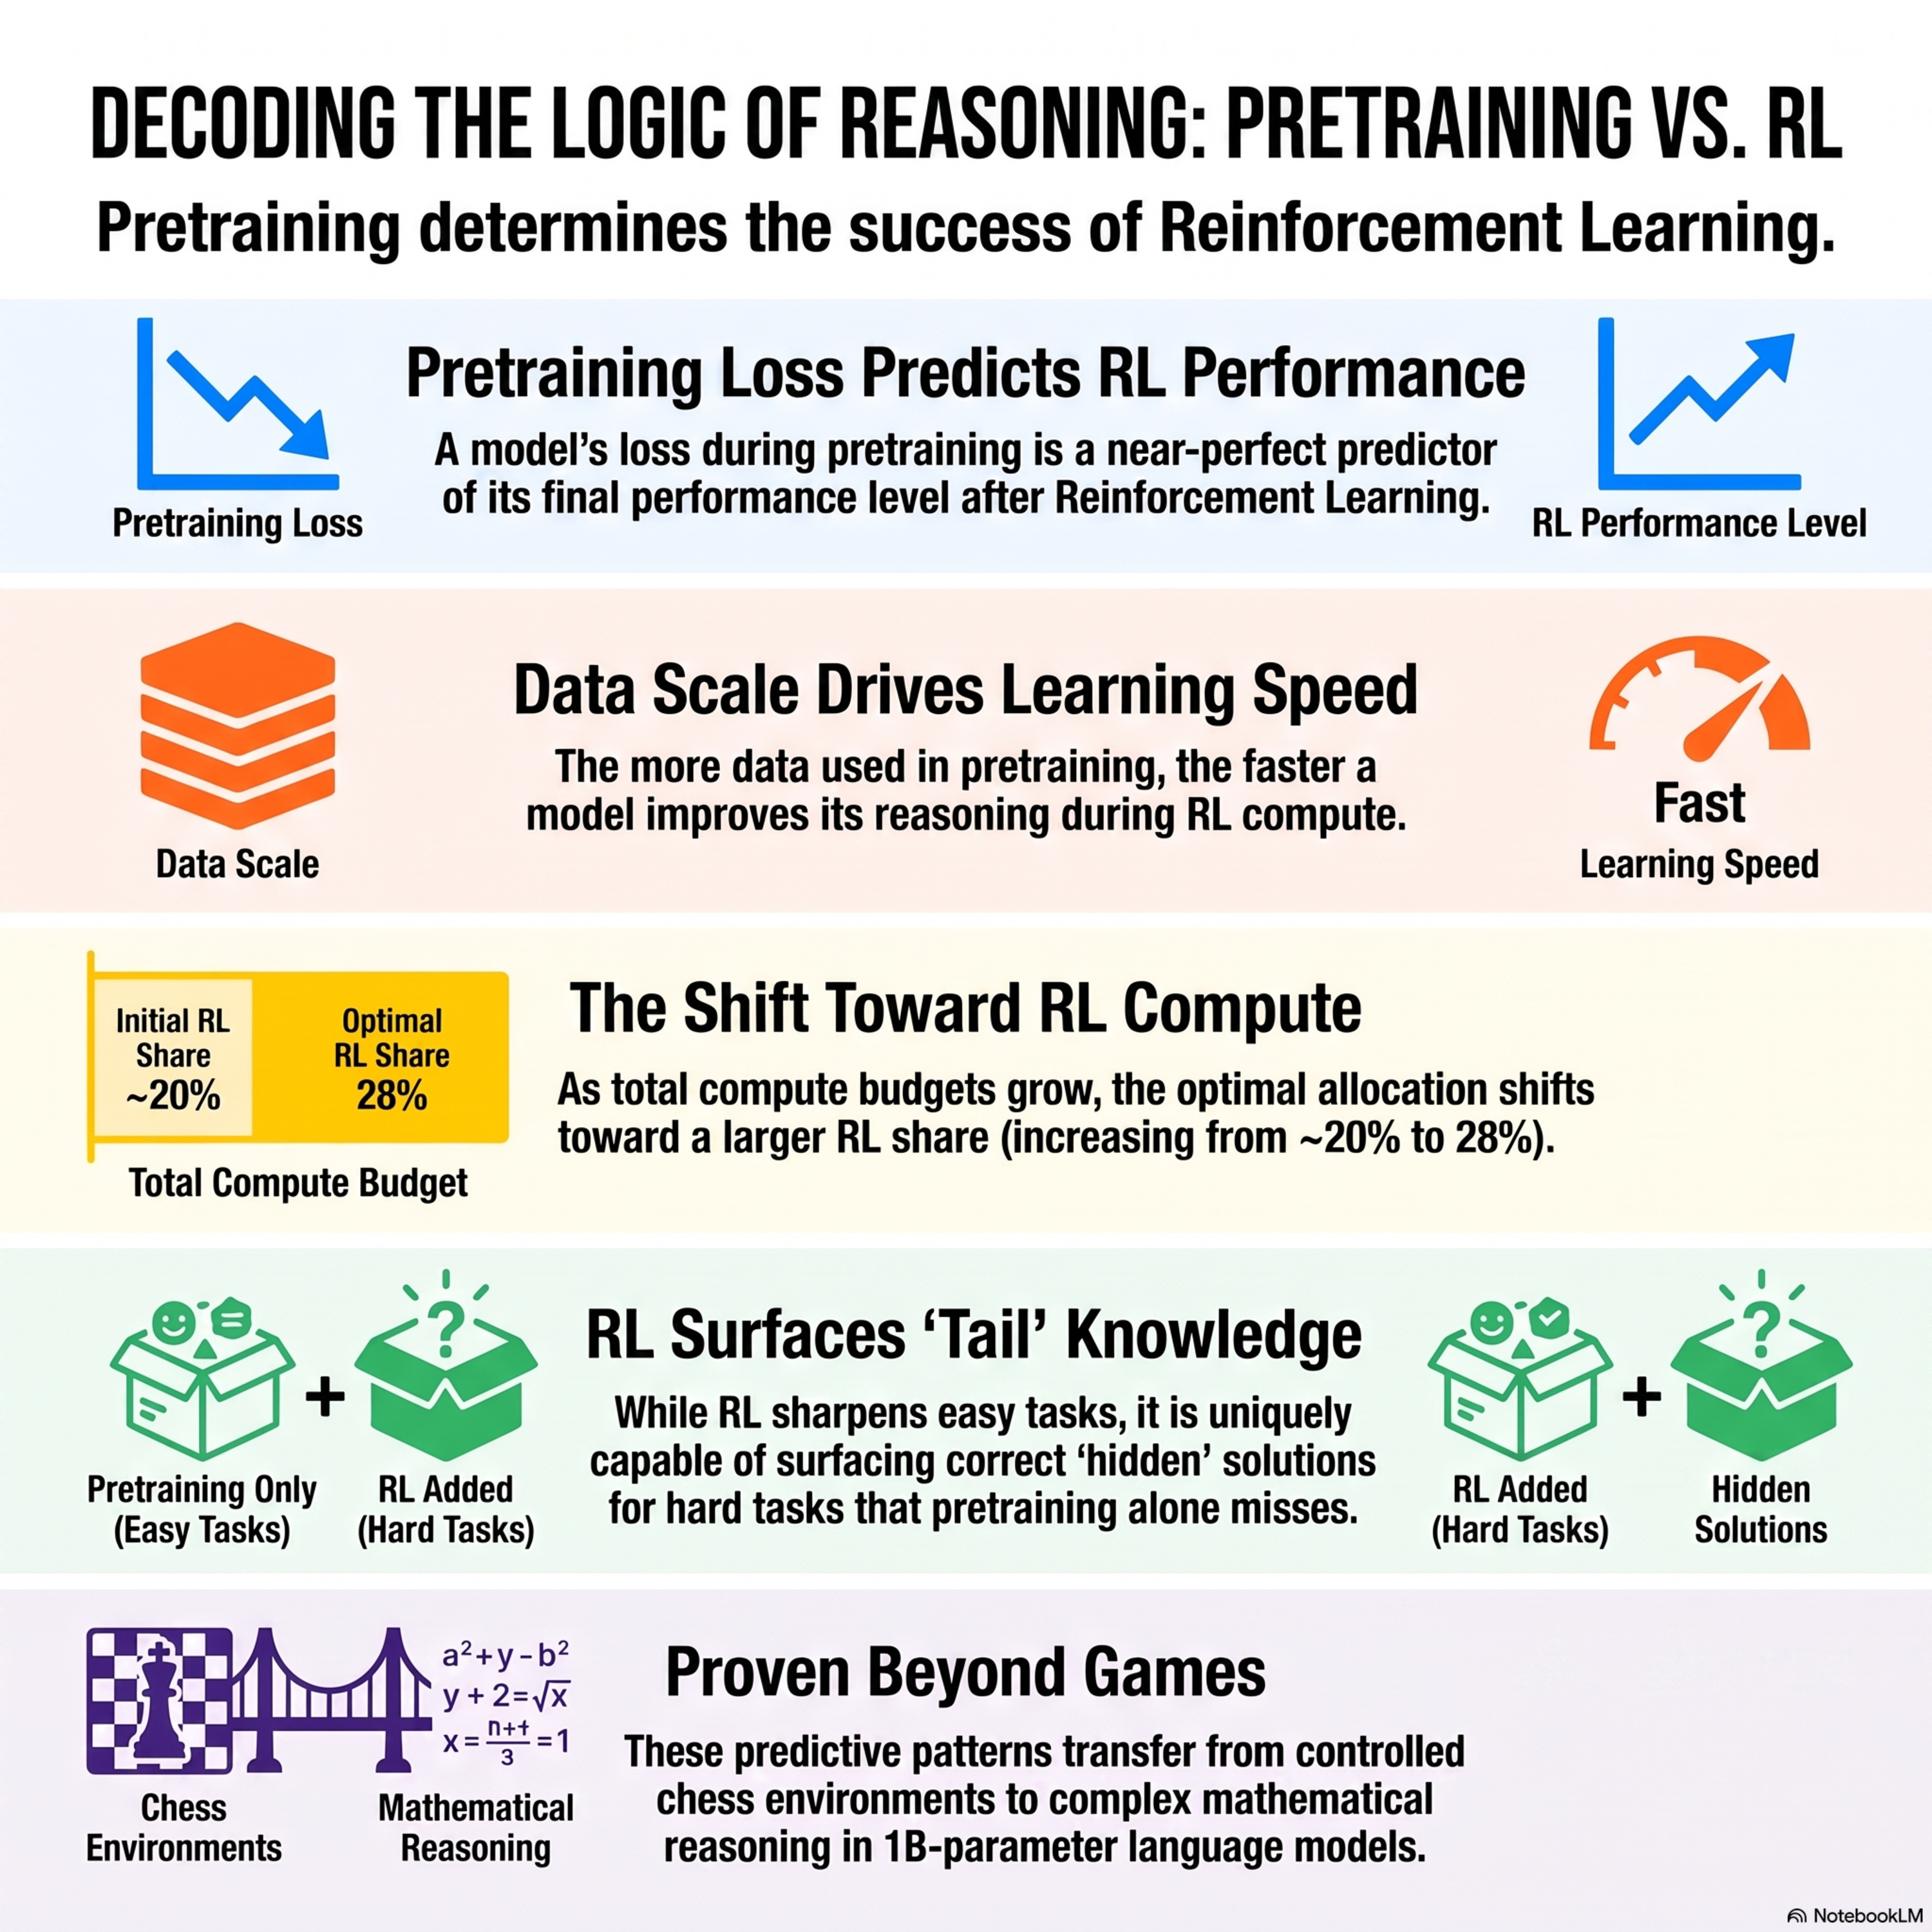
Researchers utilized chess as a controlled testbed to investigate how pretraining choices influence the effectiveness of reinforcement learning (RL) in large language models. By systematically scaling models from 5M to 1B parameters, the study established a joint scaling law where a model's pretraining loss accurately predicts its subsequent RL performance. The findings reveal that extended pretraining not only provides a better starting point but also increases the speed at which a model improves during RL training. Mechanistic analysis showed that while RL amplifies correct moves on simple tasks, it can also surface previously hidden solutions on difficult problems. Furthermore, the authors demonstrated that these predictive patterns transfer to the math domain, suggesting the results are applicable to broader reasoning tasks. Ultimately, the study suggests that as total compute budgets grow, a larger share of resources should be allocated to the RL phase.
Embed this episode
No transcript yet.