
EPISODE · Jul 15, 2026 · 22 MIN
What Does Thompson Sampling Optimize?
from Best AI papers explained · host Enoch H. Kang
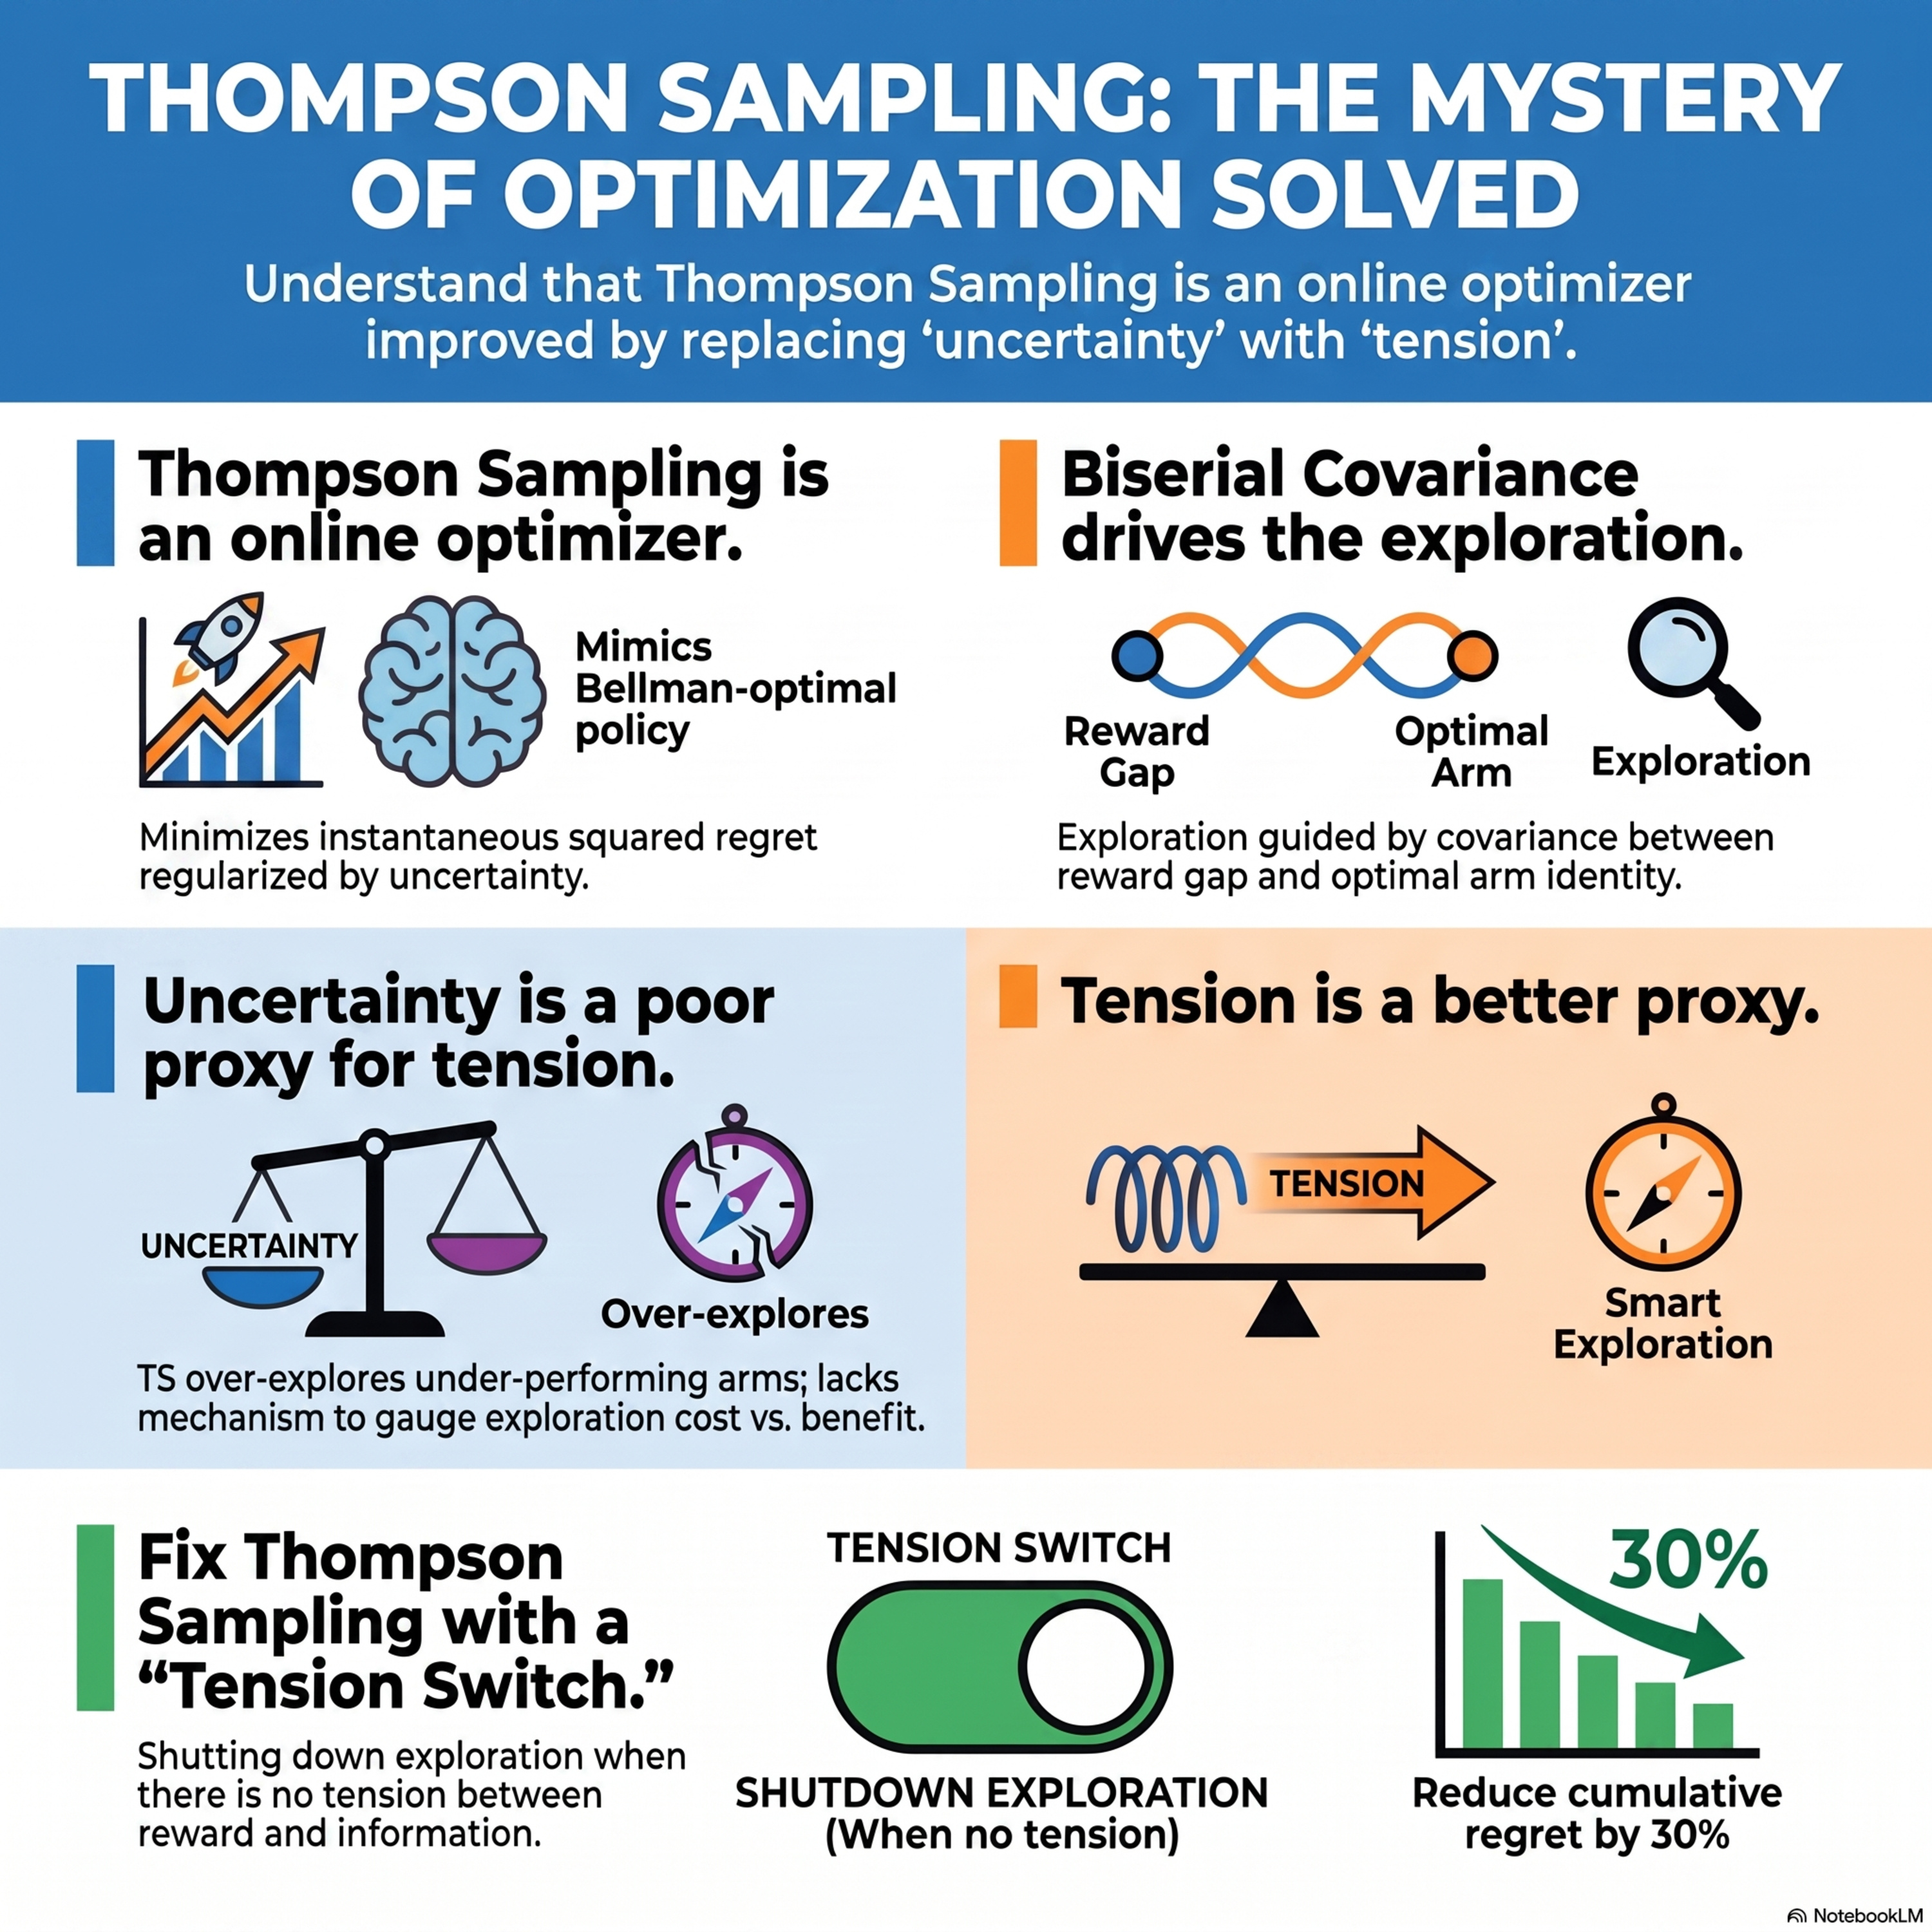
This research paper investigates the underlying mechanisms of Thompson Sampling, a popular bandit algorithm, by reframing it as an online optimization process. While traditionally viewed as a simple heuristic, the authors prove that Thompson Sampling actually minimizes instantaneous squared regret regularized by a specific measure of residual uncertainty. By comparing this mechanism to a Bellman-optimal benchmark, the study identifies a performance gap caused by Thompson Sampling's failure to account for the "tension" between exploration and exploitation. To address this, the authors propose a principled fix that adaptively shuts down exploration when the leading arm also provides the most information. Ultimately, this framework provides a theoretical compass for improving randomized algorithms by treating policy design as regularizer engineering.
Embed this episode
Ready to play
What Does Thompson Sampling Optimize?
No transcript for this episode yet
Similar Episodes
No similar episodes found.