What happened with sparse autoencoders?
from Best AI papers explained Hosted by Enoch H. Kang
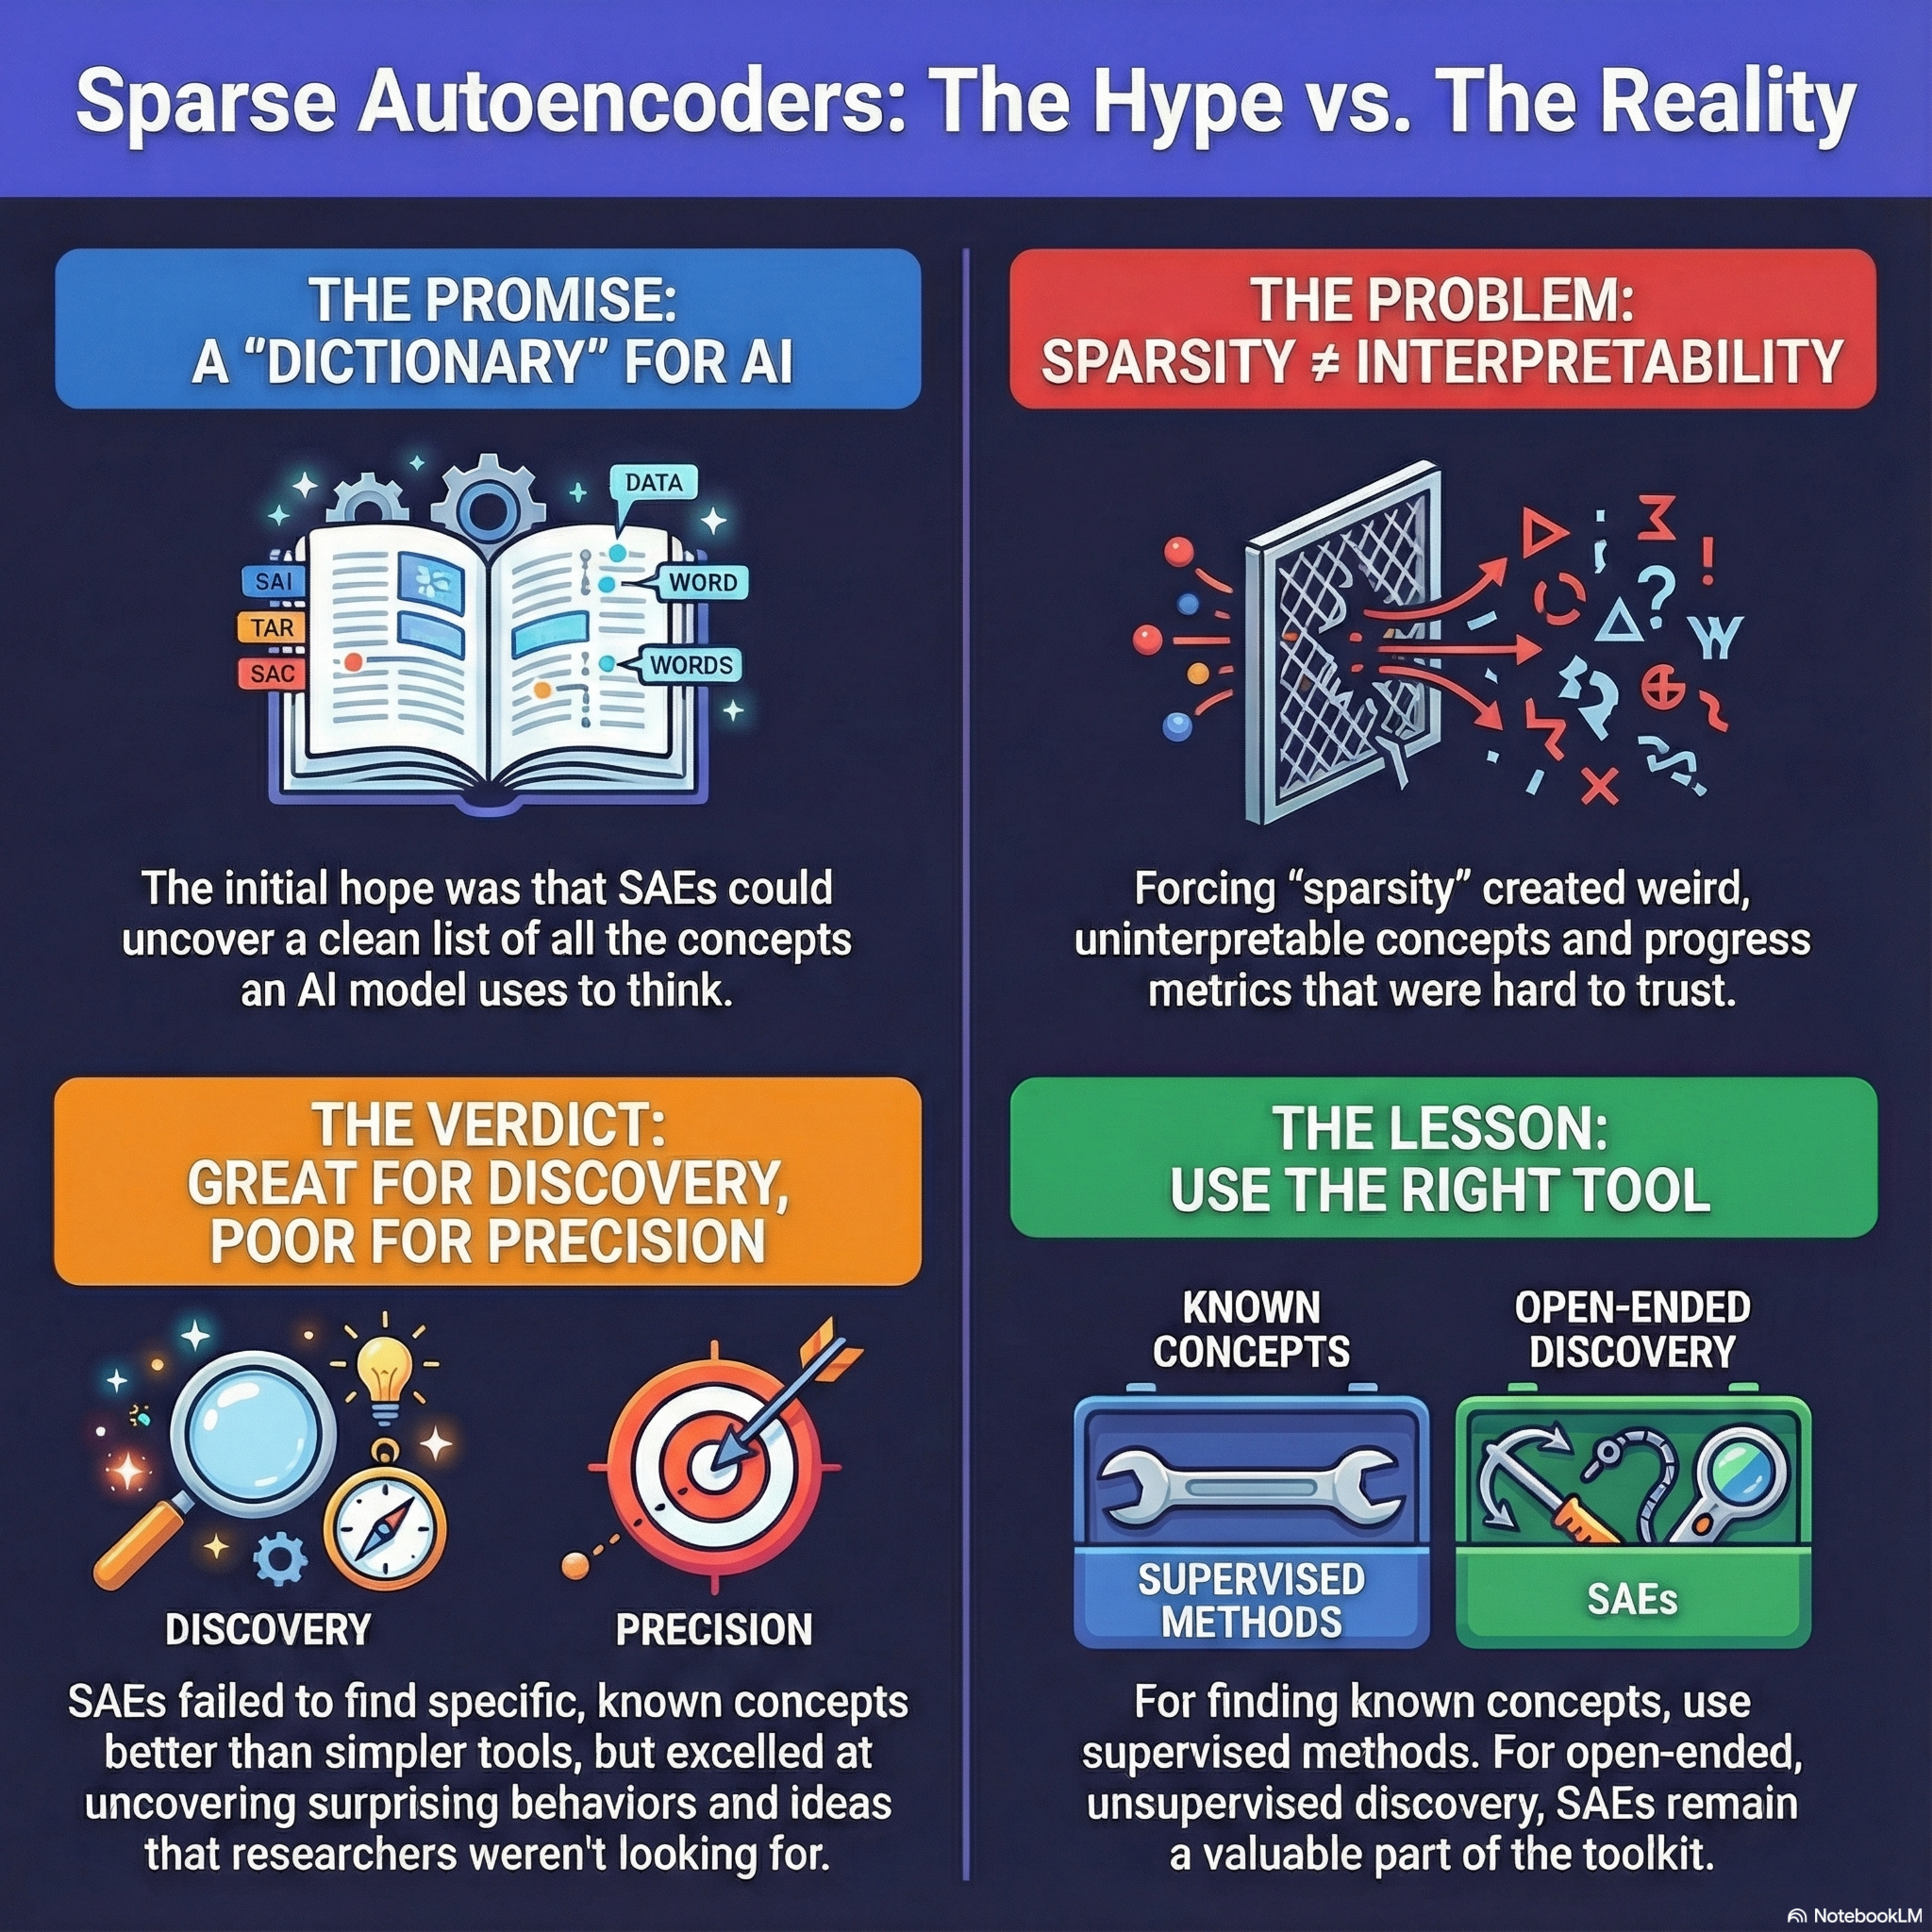
We cover Neel Nanda (Google DeepMind)'s discussion on efficacy and limitations of Sparse Autoencoders (SAEs) as a tool for unsupervised discovery and interpretability in large language models. Initially considered a major breakthrough for breaking down model activations into interpretable, linear concepts, the conversation explores the subsequent challenges and pathologies observed in SAEs, such as feature absorption and the difficulty of finding truly canonical units. While acknowledging that SAEs are valuable for generating hypotheses and providing unsupervised insights into model behavior—especially when exploring unknown concepts—the speaker ultimately concludes that supervised methods are often superior for finding specific, known concepts, suggesting that SAEs are not a complete solution for full model reverse engineering. Newer iterations like Matrioska SAEs and related techniques like crosscoders and transcoder-based attribution graphs are also examined for their ability to advance model understanding, despite their associated complexities and drawbacks.
Embed this episode
No transcript yet.