When Agents Slow Down: Understanding LLM Agents’ Test-Time Strategies via Elo-per-token Analysis
from Best AI papers explained Hosted by Enoch H. Kang
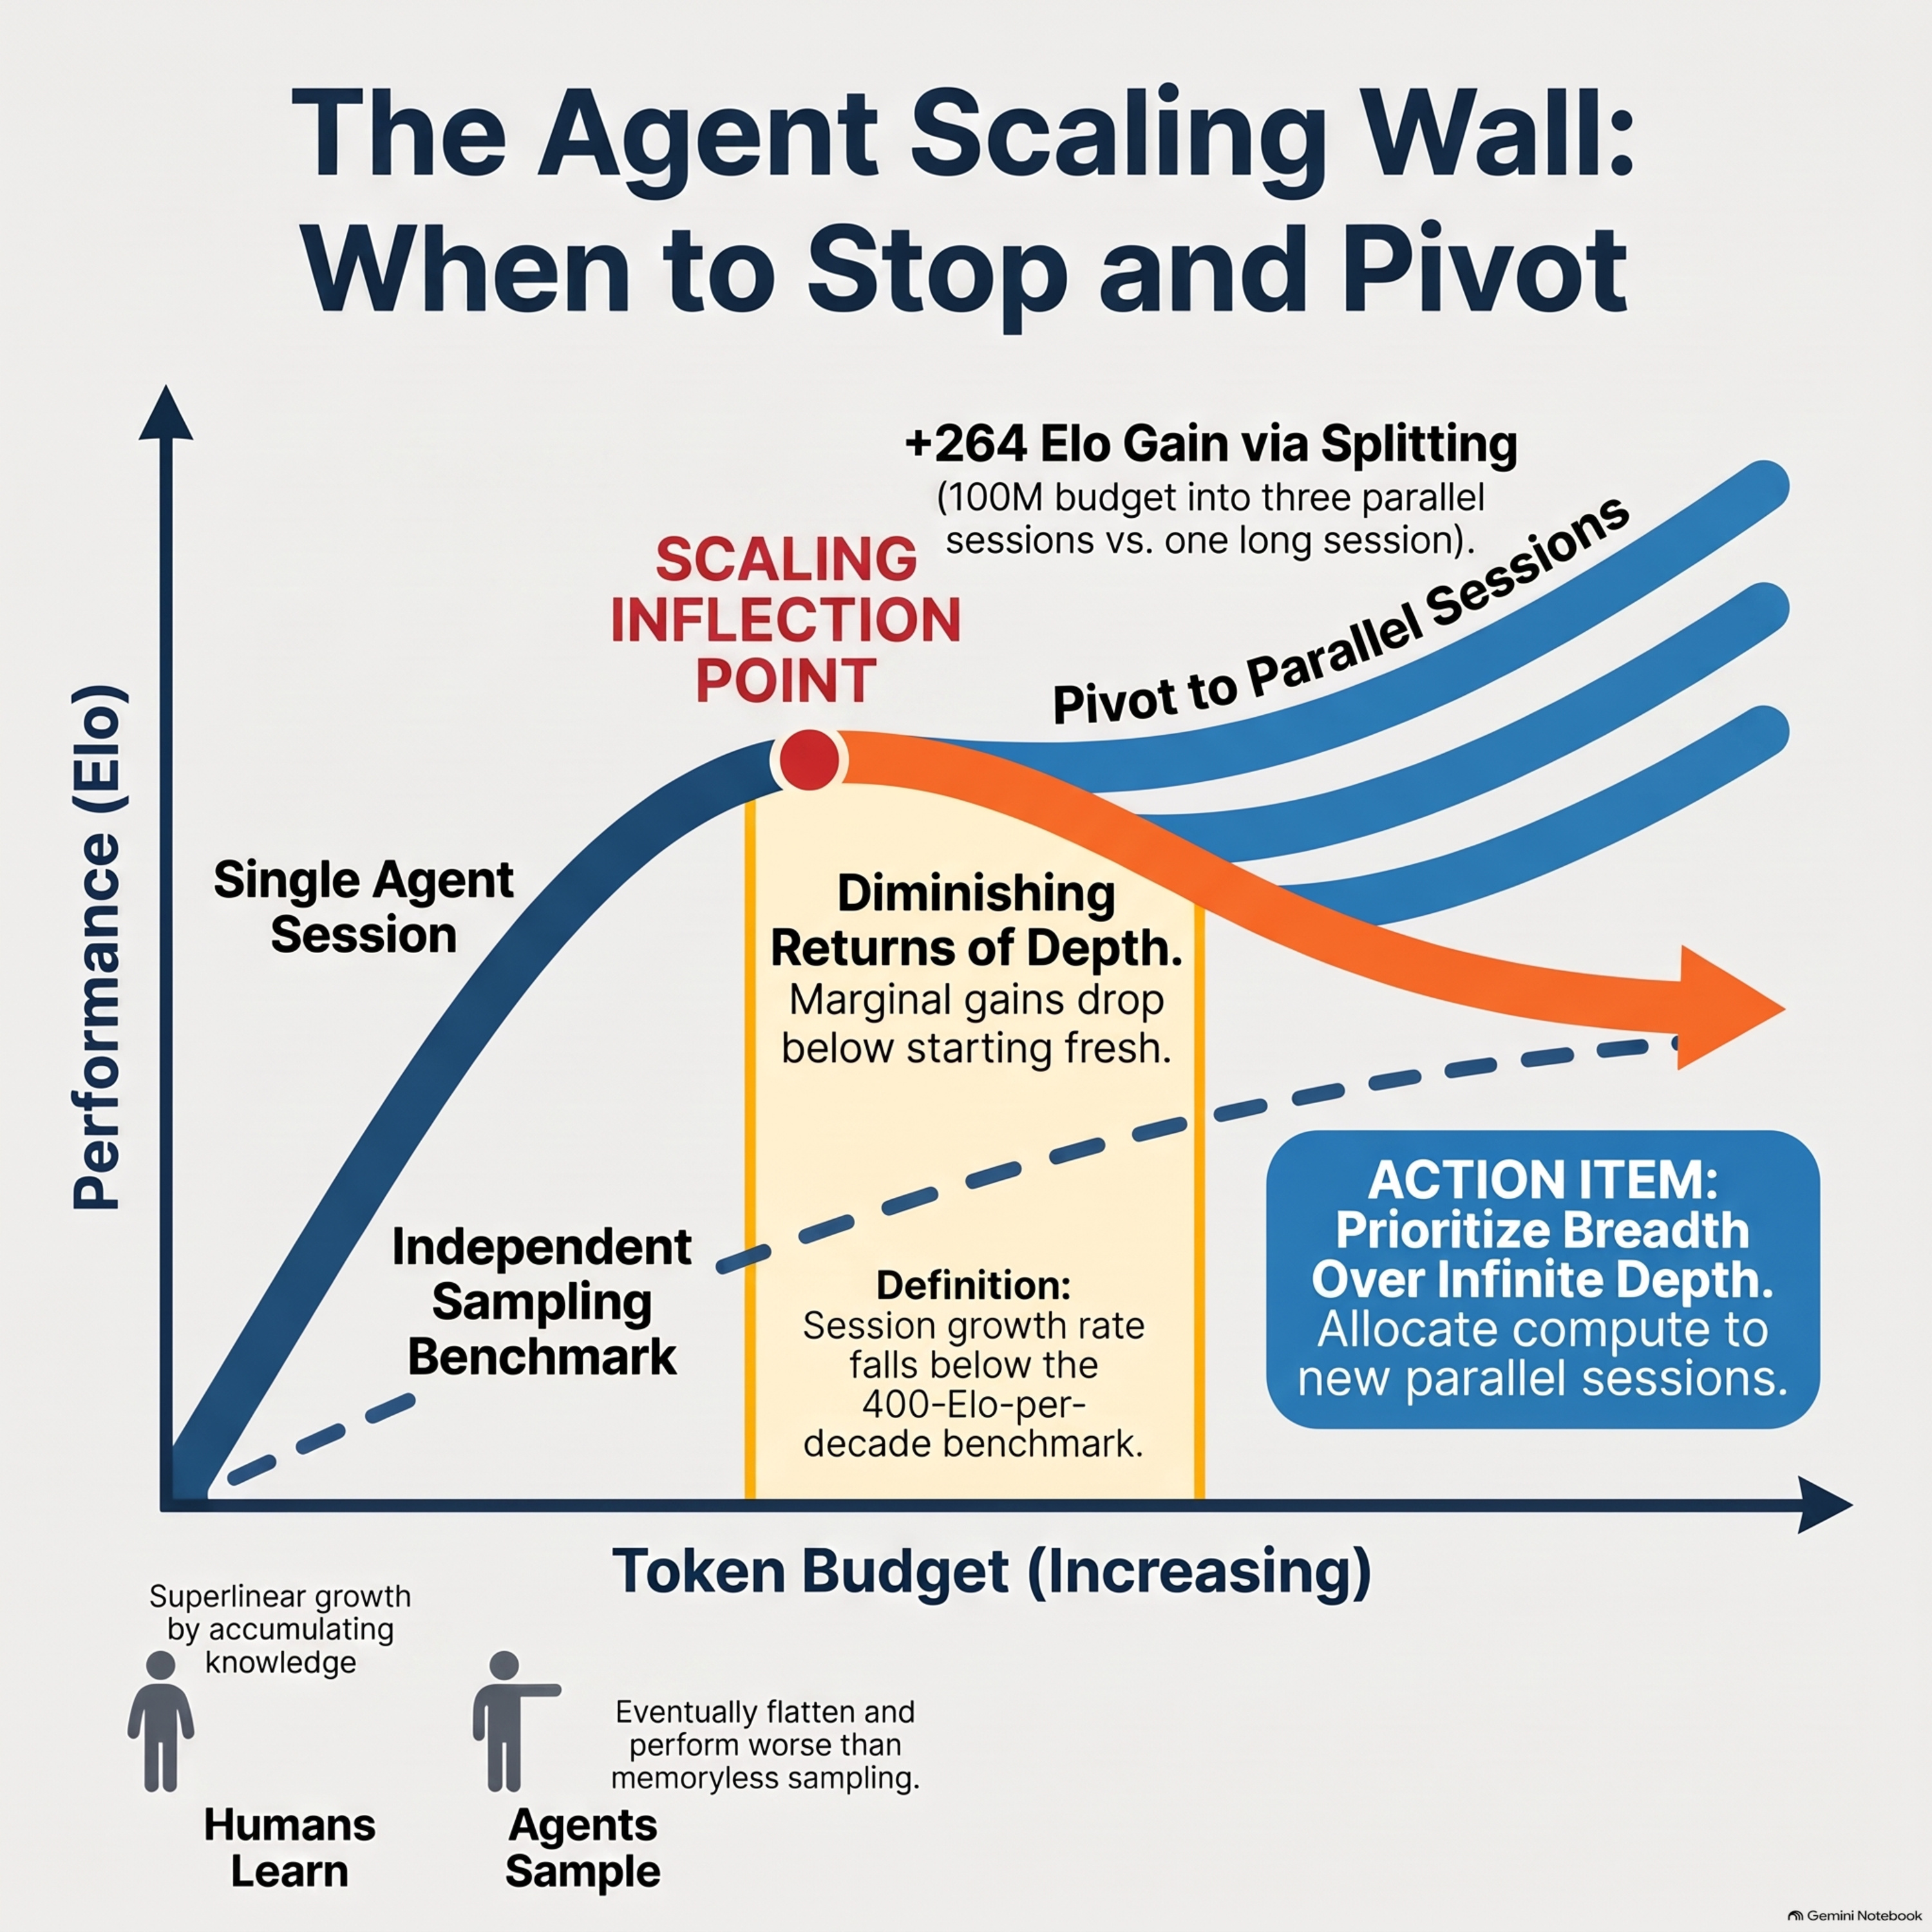
This paper introduces Elo-per-token analysis, a novel framework for measuring how the performance of large language model agents scales with increased inference-time computation. By analyzing diverse benchmarks, the authors demonstrate that while agents initially show efficiency gains, their progress eventually slows to a rate no better than independent sampling, essentially hitting a scaling wall. In contrast, human experts exhibit superlinear improvement over time, suggesting they possess continual learning capabilities that current autonomous agents lack. The study identifies a scaling inflection point, which marks the specific budget where extending a single agent session becomes less effective than starting a new one. Utilizing this metric, the researchers developed an allocation rule that optimizes performance by splitting large token budgets across multiple parallel sessions. This strategy significantly boosts results on complex tasks, providing a practical method for managing computational resources in agentic workflows.
Embed this episode
No transcript yet.