
EPISODE · Jan 14, 2026 · 38 MIN
When the LLM Programs Its Own Thinking
from Rooted Layers · host Petros Lamb
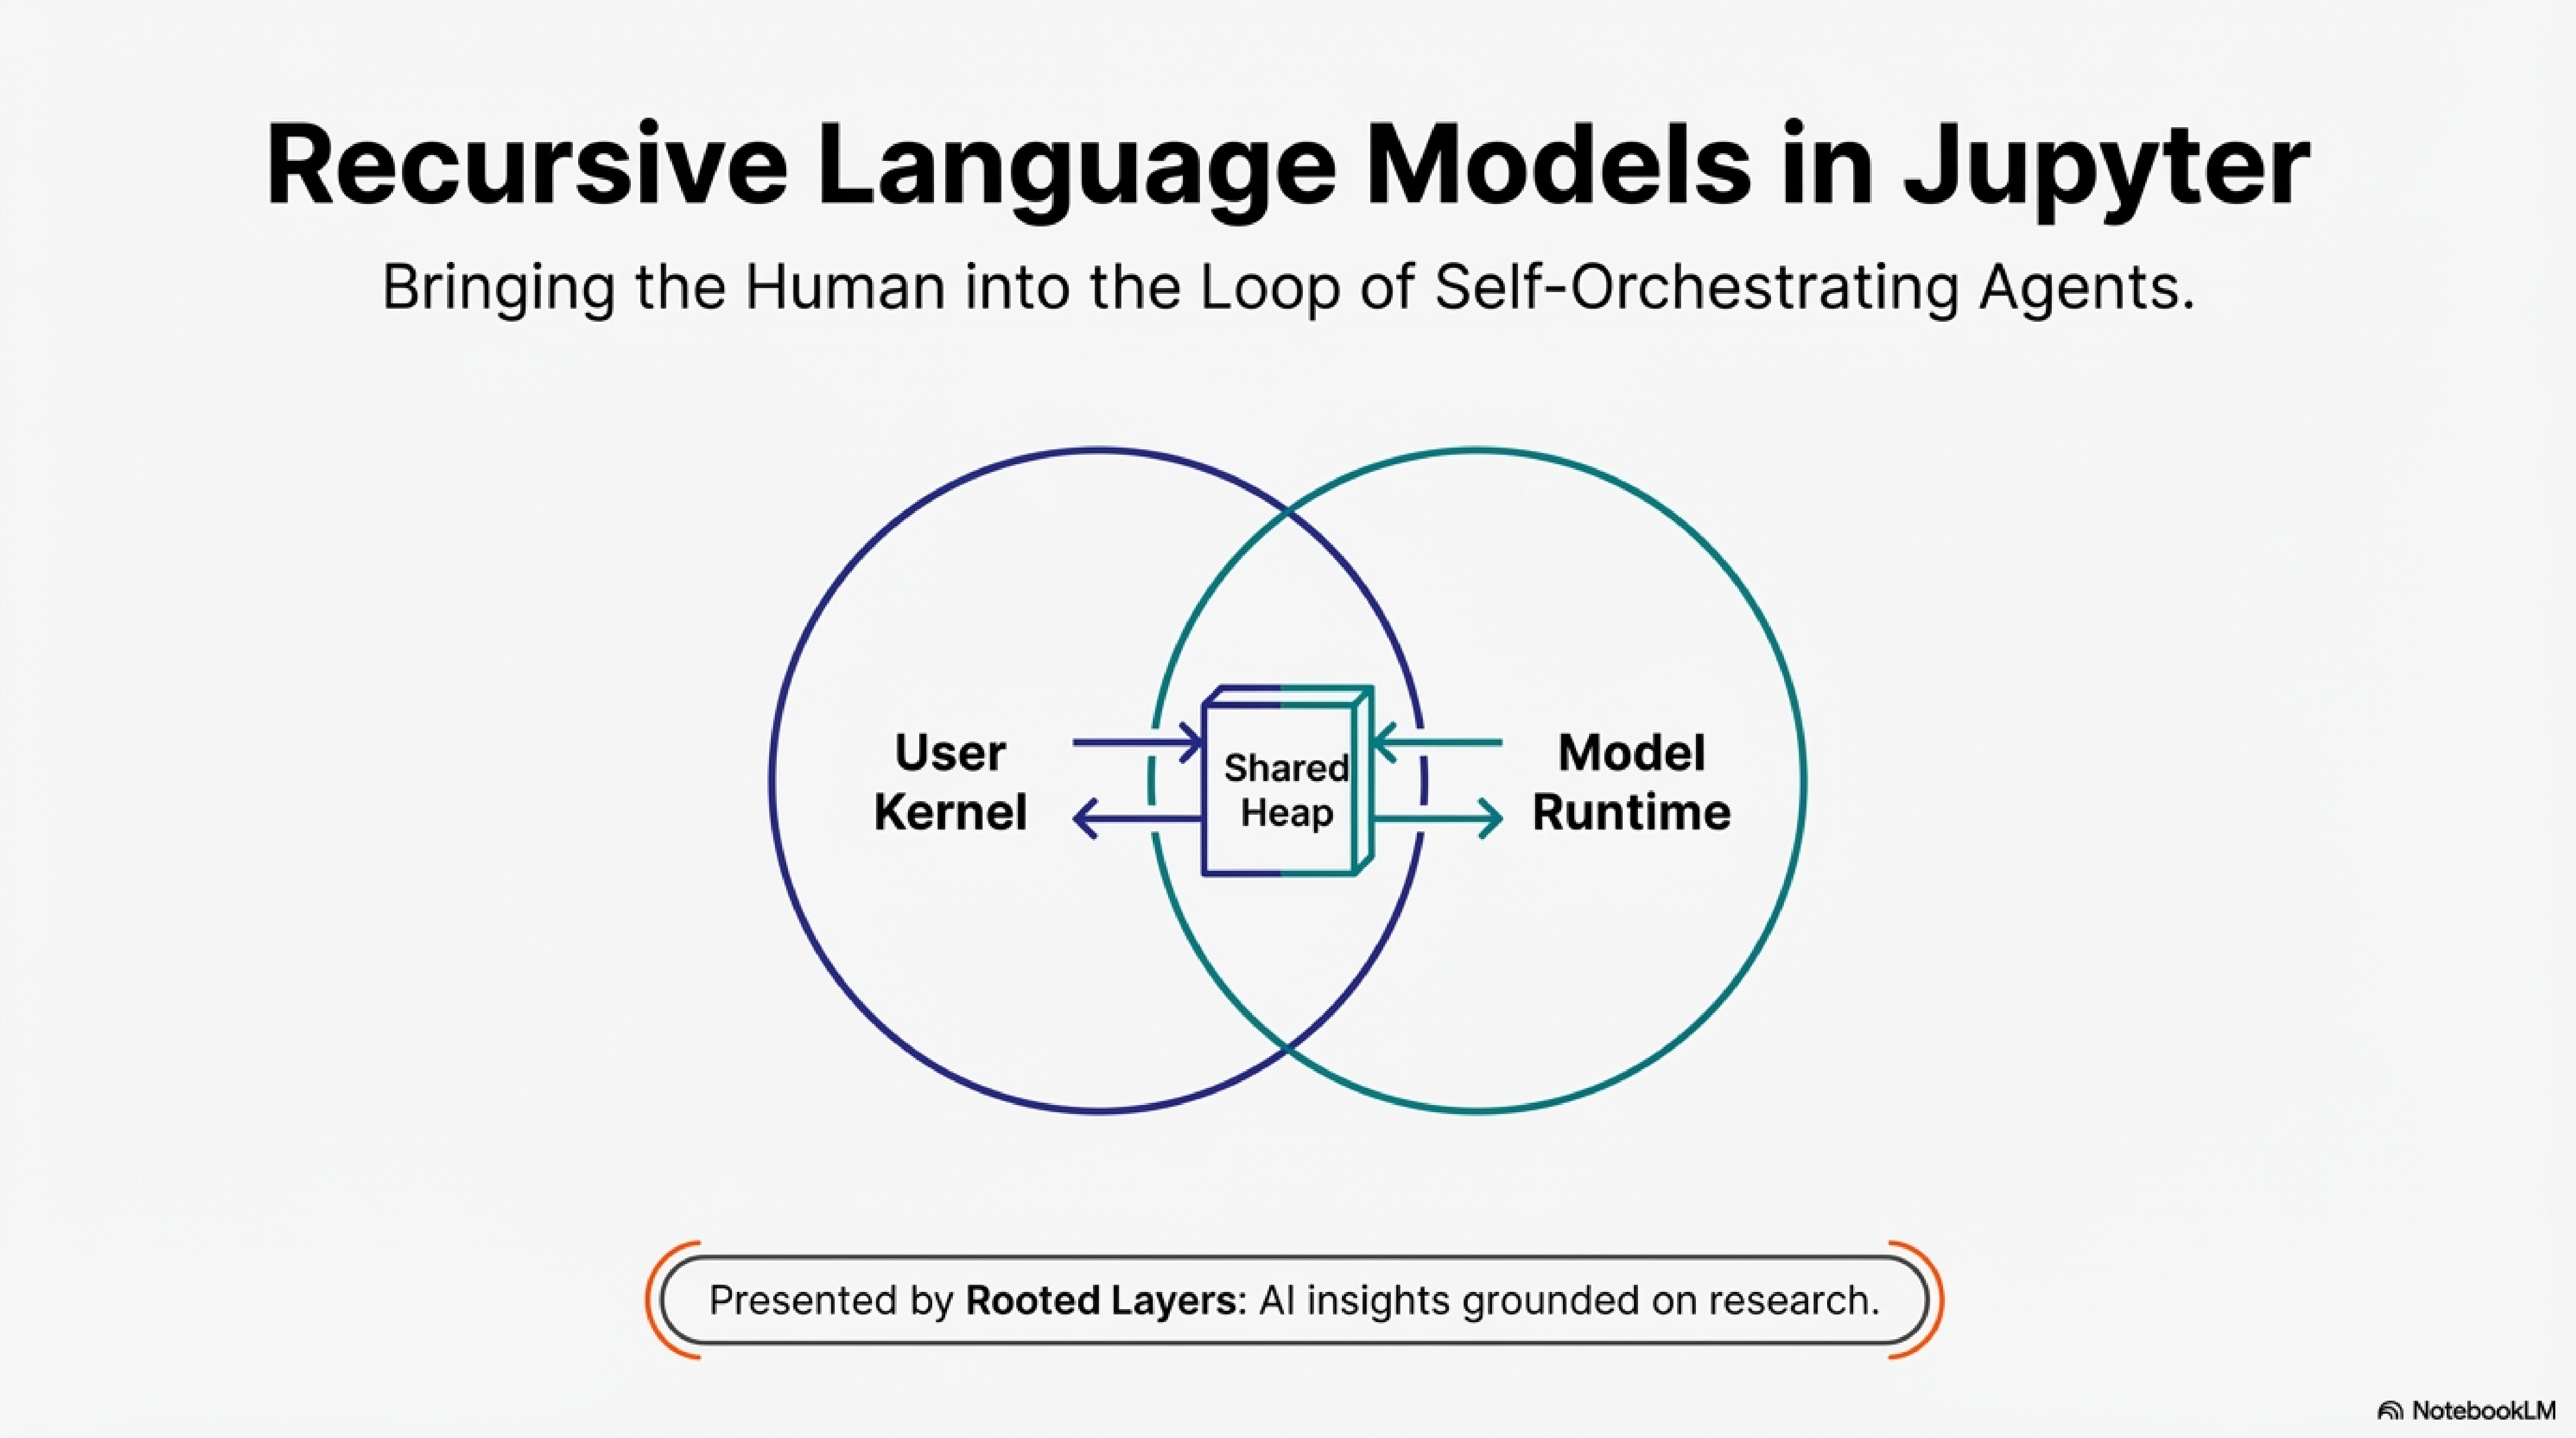
Process 6-11M tokens using 128K context models. Recursive Language Models externalize prompts as queryable variables instead of cramming them into context windows. This video breaks down RLMs from MIT and shows the Jupyter integration I built for debugging self-orchestrating models. When the model writes its own decomposition strategy and gets it wrong, you need to see what happened. The integration puts human and model in the same REPL with inline traces and runnable notebooks. Covers: the RLM paradigm vs CodeAct/THREAD/ReDel, three sync modes for namespace sharing, trace artifacts, real limitations including cost variance and non-isolated execution. Blog post: https://lambpetros.substack.com/p/when-the-llm-programs-its-own-thinking GitHub: https://github.com/petroslamb/rlm (or in the original repo is PR #46) This is a public episode. If you would like to discuss this with other subscribers or get access to bonus episodes, visit lambpetros.substack.com
Embed this episode
Ready to play
When the LLM Programs Its Own Thinking
No transcript for this episode yet
Similar Episodes
No similar episodes found.